Ethical and Legal Boundaries of Web Scraping for AI
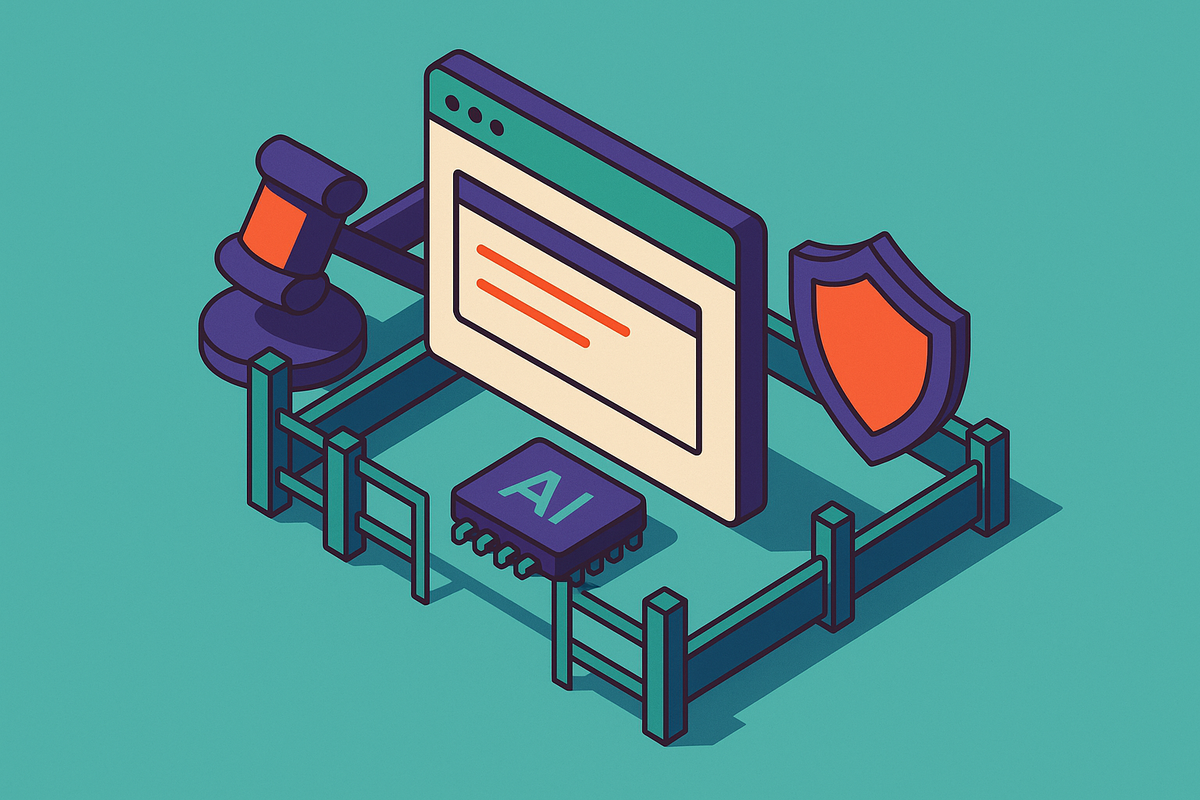
Courts are still drawing lines between scraping access and what you do with the data afterward.
Vera Whitfield
Section
8 stories in AI Web Scraping.
Courts are still drawing lines between scraping access and what you do with the data afterward.
Use API calls first, browser automation only when the API is locked down.
Web scrapers face multi-layered detection systems designed to block automated access.
Forget total pages crawled; focus instead on which URLs matter most.
Preserve document structure through proper HTML-to-Markdown conversion for better LLM reasoning.
AI agents silently fail on JavaScript-heavy sites until the token bill arrives.
Self-hosted scrapers hide massive maintenance costs that managed APIs eliminate.
Splitting web scraping from LLM orchestration prevents silent failures on bad data.