JavaScript-Rendered Content Extraction for AI Agents
AI agents silently fail on JavaScript-heavy sites until the token bill arrives.
JavaScript rendering broke web scraping years ago. Now it's breaking AI agents in a different, more expensive way: silently, at scale, and nobody notices until the token bill shows up. Any team putting an agent on the open web has to fix this before the agent reasons about anything at all, because the fetch layer is the floor everything else stands on. Get it wrong, and every layer built on top inherits the rot.
Server-rendered HTML used to mean what you fetched was what a user saw. That model is mostly dead now. Many high-value sites ship an almost-empty HTML document and build the actual page in the browser, after the fact, with JavaScript. A raw HTTP request against a modern e-commerce site, a job board, or a SaaS pricing page often comes back as a skeleton: some div tags, a handful of script references, maybe a loading spinner. The prices, the listings, the article text, none of it is there yet.
A few patterns cause most of this:
- Single-page apps that load a blank page first, then call an API to fill it in
- Infinite scroll and lazy-loaded sections that only fire when a real scroll event hits them
- Content stuck behind "Load More" buttons, tabs, or filters that need a click to trigger
- Data streamed in through WebSockets or XHR calls well after the page technically "loads"
Open DevTools on any of these pages and everything looks fine. The DOM is full, the fields are all there, the product grid renders exactly like it should. That's the trap. DevTools shows the page after JavaScript has already run, but a plain HTTP fetch never runs any JavaScript at all. A developer staring at the Elements panel is looking at content that flatly does not exist in the response their scraper actually gets back.
This isn't some fringe case affecting a few oddball sites. E-commerce, financial data platforms, SaaS product pages, job boards: these are common categories agents get sent to, and they're JavaScript-first by design. The gap between what a browser shows and what an HTTP client gets back is the default condition of the modern web, not some exception to plan around later.
How the JS rendering gap becomes an agent failure, not just a scraping inconvenience
A person doing manual scraping notices an empty response right away, looks at the output, sees nothing useful, and goes to fix it. An agent doesn't have that reflex. It reasons forward from whatever it's handed, treating garbage input as valid input, and the failure stays invisible until something downstream breaks in a way that's hard to trace back to the source.
Here's the typical sequence. The agent picks a URL and calls its fetch tool. The fetch tool comes back with either a bot-detection interstitial or a blank JavaScript shell. Nothing throws an error, so the tool call reports success. The agent hands that payload to the model as if it were real page content. The model then tries to pull product data out of a Cloudflare challenge screen or an empty div, fails, and the agent decides the data must not exist. From there it replans, retries, or just gives up, burning tokens the whole way through.
Agents run into failure modes a human scraper never has to think about. Ask the model to write a CSS selector and it produces something plausible-looking with no real relationship to the page's actual structure, drifting further off as the site's layout changes while the agent reports "zero results" with total confidence. Without an explicit stop condition, an agent hammers the same captcha or 403 response over and over until it burns through its token budget, often the single biggest cost driver in agent runs that go sideways. Session loss shows up mid-task too: the agent logs in on step one, and by step five session state is lost, the site sees a brand-new visitor, and a fraud check fires. A datacenter IP can also trigger silent localization, so the agent pulls prices for the wrong country and the model has no way to know the numbers it's reading are wrong.
None of this is a reasoning failure. The model can work perfectly and still produce garbage, because the fetch layer cracked before the model ever got a chance to think. Every layer above it looks broken, but the actual break happened at the network request, not in the model's head.
There's a cost angle too, and it's not small. Raw HTML handed straight to a model is mostly noise: nav bars, cookie banners, tracking scripts, ad containers. The model burns tokens reading all of that before it even gets to the one paragraph or one price it actually needed.
The anti-bot layer that compounds JS rendering into a two-headed problem
JavaScript rendering is only half the obstacle, and treating it as the whole problem is exactly how these projects fail. The sites worth scraping don't just need a browser that can run JS. They actively check whether the thing making the request behaves like a real person on a real browser, and they reject it the moment it doesn't.
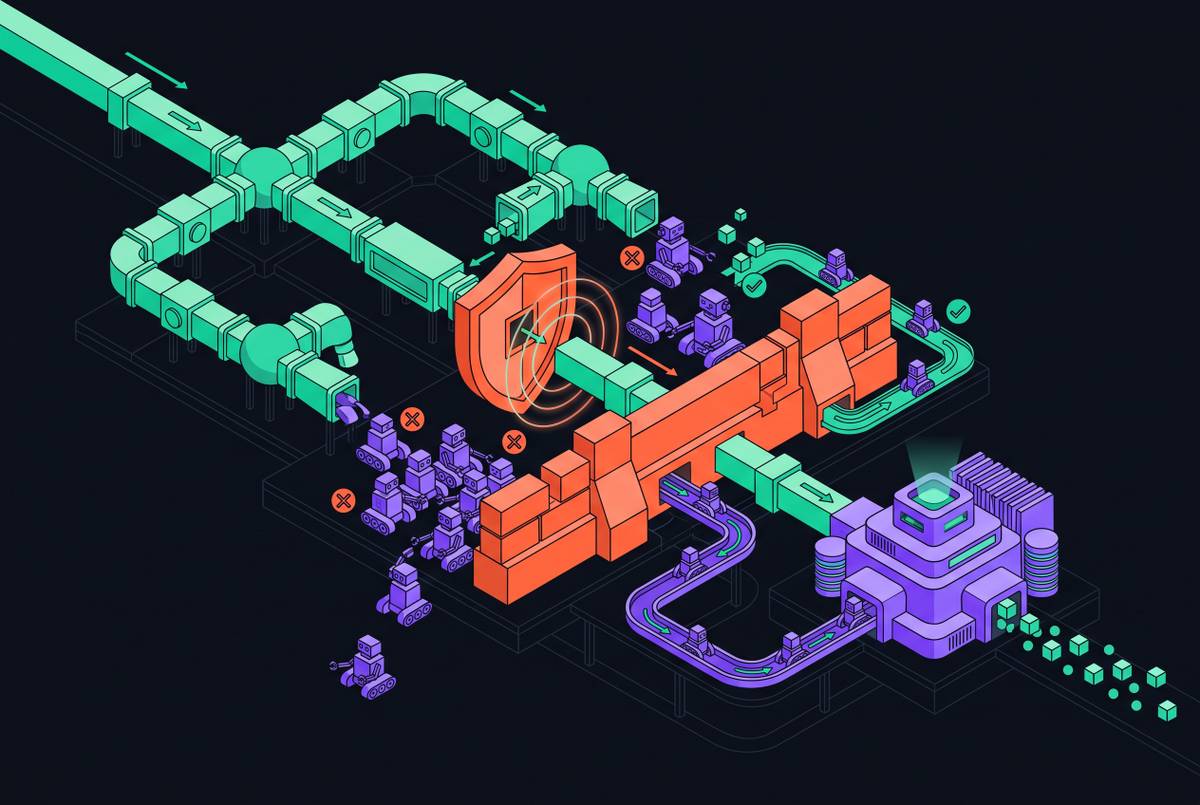
Anti-bot systems are a good illustration of what agents are actually up against. Detection can flag a request based on low-level network signals before a single byte of the page has even been served. Turnstile adds an interactive challenge, a proof-of-work computation or something that expects real user interaction, and a headless browser with no input simulation gets stuck right there. Behind that sit challenge pages, which inject JavaScript tests that check browser API behavior, DOM changes, and timing patterns. Fail any of it and the response is a 403 or an endless redirect loop, never the page itself.
The surface being scored has grown well past request headers. TLS fingerprint, HTTP/2 frame order, mouse movement patterns, which JavaScript APIs are available: all of it gets weighed together, in real time. An agent that renders JavaScript perfectly but can't pass behavioral fingerprinting still fails. Both problems need solving at once. Solving one and ignoring the other buys nothing, and this is exactly where most homegrown agent-fetch setups quietly die.
Teams building this themselves in 2026 are generally reaching for the same handful of tools. Nodriver skips the automation fingerprint entirely by removing the signals that betray automated control, and SeleniumBase's UC Mode patches the specific signals that give chromedriver away. Camoufox wraps Firefox with Playwright, intercepts fingerprinting at the engine level, and patches the tells in Firefox's headless mode; on a VPS with no real display, it falls back to a virtual one. Proxy choice matters more than proxy volume here: rotating datacenter IPs cycle automatically but score badly against bot-risk models, while residential proxies route through real consumer connections and score far better.
The harder requirement sits underneath all of it: every layer has to agree with every other layer. TLS fingerprint, browser signals, JavaScript behavior, mouse and scroll patterns all need to tell the same story. One clean-looking layer doesn't help if it contradicts another, and detection systems exist specifically to catch that kind of mismatch. None of this is a fix-it-once job, either. Detection systems keep changing, so every technique on that list needs continuous upkeep just to keep working. Treat it as solved infrastructure and it quietly stops working a few months later, usually right when it matters most.
What a fetch layer built for agents actually needs to do
Four separate jobs make up an agent's web access, and it's tempting, and wrong, to treat them as one job.
- Fetching. Render the JavaScript, get past the anti-bot checks, come back with what a real visitor would actually see.
- Observation. Turn that content into something a model can work with: clean Markdown or structured JSON, not a wall of raw HTML tags.
- Sessions. Hold state across multiple steps: staying logged in, keeping filters applied, working through a paginated list or a string of "Load More" clicks.
- Tool integration. Wrap all of it into one interface the agent framework can call the same way, every single time.
Format matters more than it sounds like it should, and this is the part most teams get backwards: they spend their effort tuning the model when the real bottleneck sits one layer down. The NEXT-EVAL 2025 benchmark found large language models can hit F1 scores above 0.95 on structured web extraction, but only when the input going in is properly formatted. The model was never the problem. The extraction layer was.
"Properly formatted" means a few concrete things: navigation menus, cookie banners, and ad injections stripped out before the model ever sees them; heading structure, lists, and tables kept intact so the model can find a field without guessing where it lives; and, for structured pulls, a JSON schema that forces the model to flag a missing field instead of inventing a value to fill the gap.
Sessions bring requirements static scrapers never had to deal with. Login state has to survive across separate tool calls, not just one request. The proxy IP has to hold steady through an entire session, since a mid-task IP change is exactly what trips fraud detection. And sometimes the agent needs to click, type, and scroll, not just read a page passively.
The right default: use a scraping API for anything read-only, and only spin up a full browser session when the agent actually needs to take action on the page. Skip that distinction and most teams end up paying full browser-session costs for jobs that only ever needed a clean text pull.
Tool integration has a deadline attached to it now, too. OpenAI adopted MCP in March 2025 and has the Assistants API scheduled to sunset on August 26, 2026. That's the whole developer ecosystem moving toward MCP-based tool integration at once. Build agent infrastructure without an MCP path in 2026, and what you've built already has a shelf life.
How the major tools handle JS rendering and agent integration in 2026
The tools in this space split along one clear line. Some hand back model-ready output on the first call. Others hand back raw HTML or a proxy connection and leave the structuring work to you, and that difference matters more than any feature comparison chart suggests.
On the first side sit platforms that turn any URL into LLM-ready Markdown, crawl entire sites, and extract structured data through a developer-defined JSON schema, all through a single endpoint. JavaScript rendering, proxy management, and anti-bot handling sit behind the scenes as infrastructure, so what the agent gets back is clean content, not raw HTML it has to parse itself. Companies like Mintlify, SiteGPT, and Sourcely run on tools built this way, using them as the data layer under their own AI products.
Scrapfly sits further toward the "developer builds the pipeline" end while still handing over a lot of the pieces. Its Web Scraping API takes render_js=True and asp=True flags for read-only agent fetches, with an anti-scraping protection (ASP) layer for harder targets. An AI Extraction API adds Templates, LLM prompts, or an Auto mode for pulling structured JSON. A Cloud Browser API with stealth and Session Resume covers multi-step workflows that need real actions taken on a page. There's also a Crawler API for site-wide RAG ingestion, SDKs for Python and Scrapy, integrations for LangChain and LlamaIndex, and both self-hosted and hosted MCP server options, plus a managed AI Browser Agent for teams that don't want to build the orchestration layer themselves.
Bright Data plays at the enterprise end, priced around $1.50 per 1,000 results, with proxy and SERP pipelines built for scale. Its Web Unlocker returns HTML, JSON, Markdown, or a screenshot, and Markdown output comes native. Custom extraction logic, though, is still on the team using it. Fine for organizations that already have parsing infrastructure in place and need scale more than out-of-the-box LLM formatting, but it's the wrong pick for a small team without that infrastructure already built.
Crawl4AI is open-source and free, and it outputs both Markdown and JSON with LLM extraction built in. It doesn't ship managed proxy infrastructure, but anti-bot detection and proxy rotation are there if a team self-hosts and wires them up. Right pick for teams that want full control and are willing to own the adversarial side of the problem directly, no shortcuts, wrong pick for anyone hoping to skip that work.
Browse.AI, with a free tier covering 100 runs, targets monitoring and no-code users: strong for scheduled page checks and change detection, weak for agents calling it programmatically at scale. Octoparse rounds out the no-code end: a free tier with limits, $83 a month for cloud-scheduled scraping, a visual point-and-click interface on desktop and cloud, output in CSV, JSON, Excel, HTML, or XML. Octoparse is built for scheduled jobs and non-technical users, not for wiring straight into an agent's tool-calling loop, and trying to force it there costs more time than it saves.
Schema-driven extraction as the right abstraction for getting JS content into AI pipelines
Handing a model raw HTML wastes tokens, and the real damage runs deeper than the token cost. It's a reliability problem first. A model's attention latches onto structural tags, hidden CSS elements, or ad content and mistakes any of it for the actual page. Worse, when a field is genuinely missing, the model doesn't reliably say so. It tends to make up something plausible-looking instead. No amount of prompt tweaking fixes that, because the input itself is broken before the prompt ever gets read.
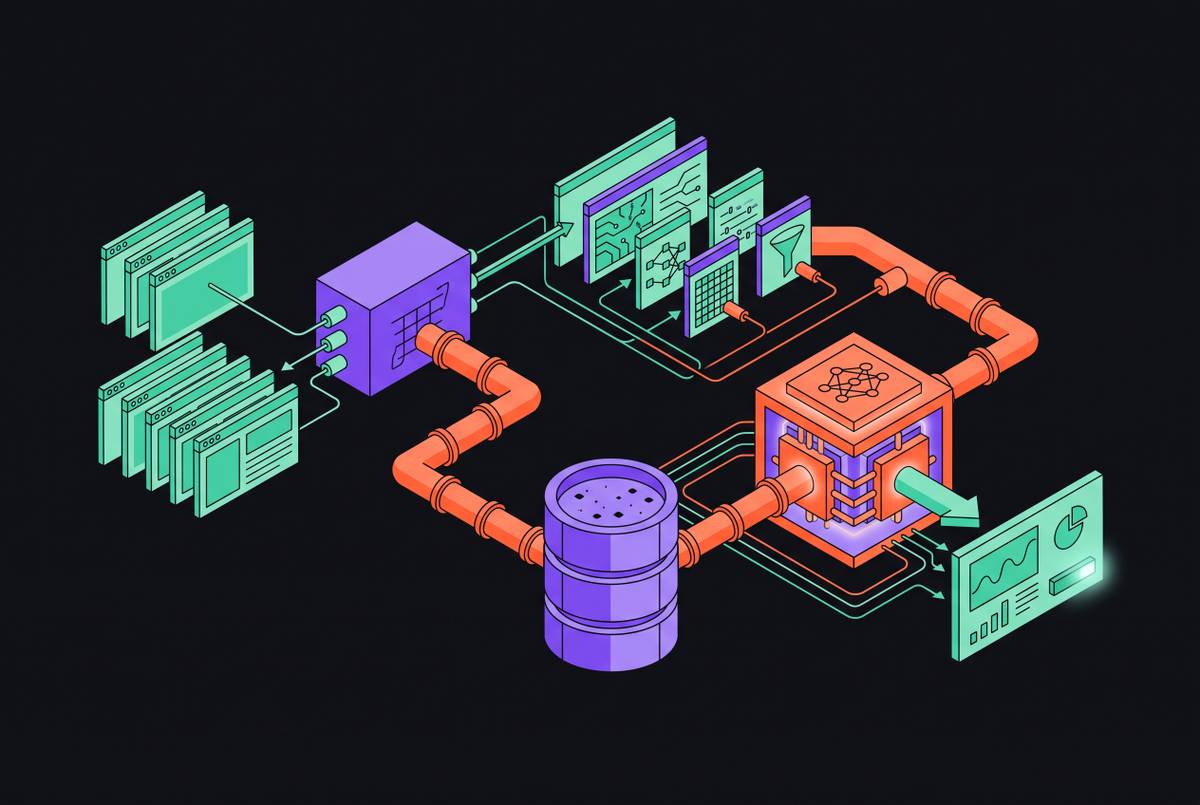
A JSON schema fixes the actual cause instead of papering over it. It works as a template that tells the model exactly which fields to pull and what type each one should be. Mark a field required, and the model either finds a real value or returns a structured null, so nothing downstream crashes on a missing key. Mark other fields optional, and their absence becomes meaningful information instead of an ambiguous gap. Because the schema is something the developer controls directly, it can change as the agent's data needs change, without touching the extraction infrastructure underneath it at all.
This isn't just enterprise plumbing anymore, either. In practice, teams applying this pattern typically wire named schema templates into their extraction calls and log every structured JSON output to a persistent store automatically. That's schema-driven extraction working as a basic, everyday tool for one developer, not some heavyweight platform feature reserved for large teams with dedicated infrastructure budgets.
The payoff for agents is simple: a schema-driven extraction call returns the same field structure every time, no matter which page it hit or how that page's HTML happened to be laid out. That consistency is what lets an agent chain calls together, retry safely, and hand data downstream without a human checking the output first. Everything upstream, the JavaScript rendering, the anti-bot bypass, the session handling, exists to feed this one narrow, well-defined output. Get that part right, and the rest of the agent's reasoning finally has solid ground to stand on.