AI Web Scraping
Ethical and Legal Boundaries of Web Scraping for AI
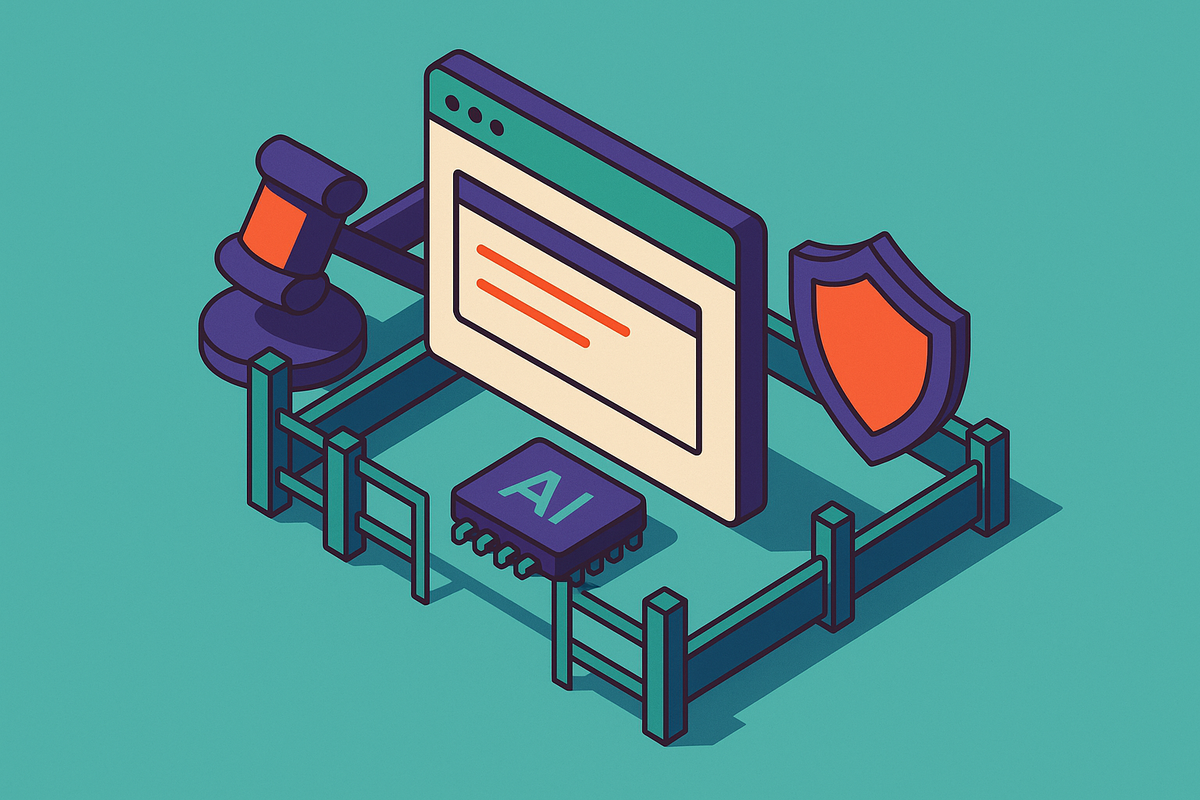
Companies face overlapping legal risks when scraping data for AI training.
Marcus Oduya
· 12 min read
Companies face overlapping legal risks when scraping data for AI training.
Reverse-engineer hidden APIs before automating—it saves compute and pipeline costs.
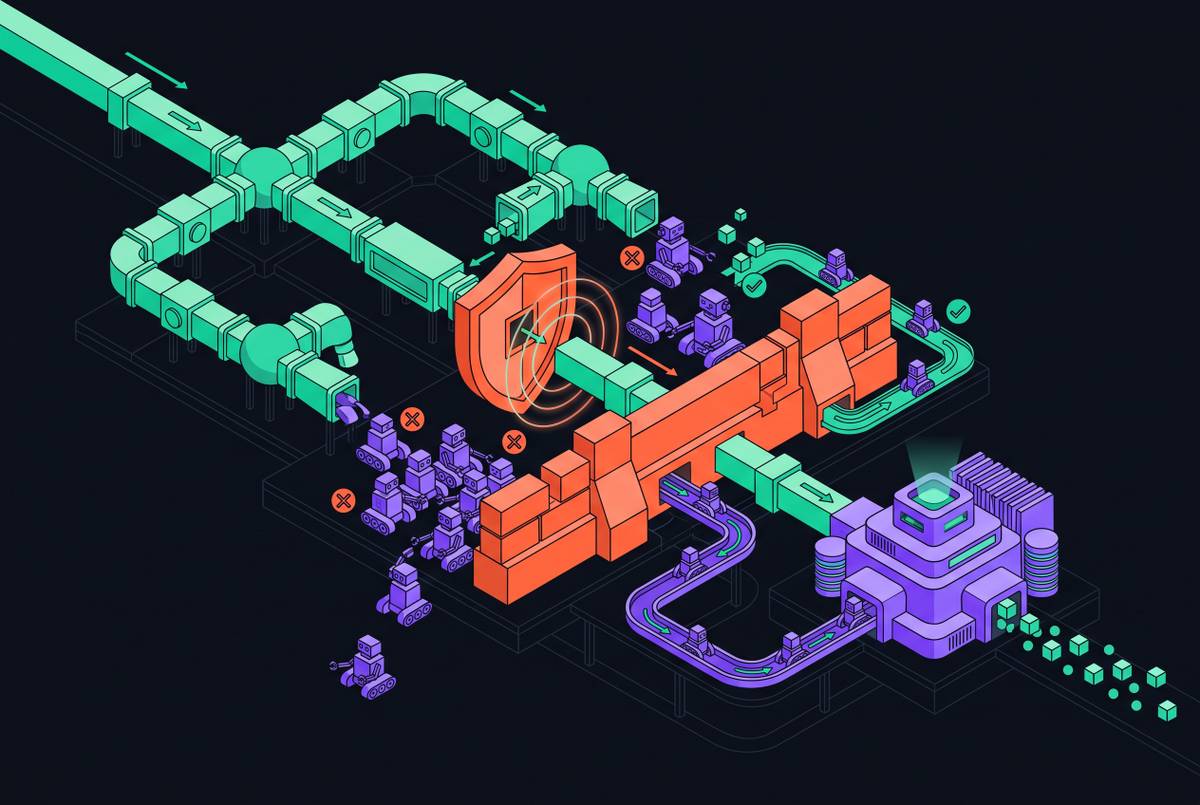
Modern anti-bot systems stack four detection layers to catch scrapers and AI agents.
Strategic crawler prioritization cuts compute waste and improves data quality for AI pipelines.
Converting scraped HTML to Markdown cuts token waste and improves retrieval quality.
Agents silently fail on JavaScript-rendered sites until token costs spike.
Managed APIs handle anti-bot detection so your team doesn't have to.
Building a proper fetch stack prevents LLM agents from reasoning on garbage data.
Live web grounding fixes RAG staleness that static indexes quietly hide away.
AI agents need typed, structured data to act reliably on live web content.
Agents fail when memory design ignores context limits and staleness.