Data Normalization After Structured Web Extraction
Values inside extracted fields need standardizing before they'll work together in AI pipelines.
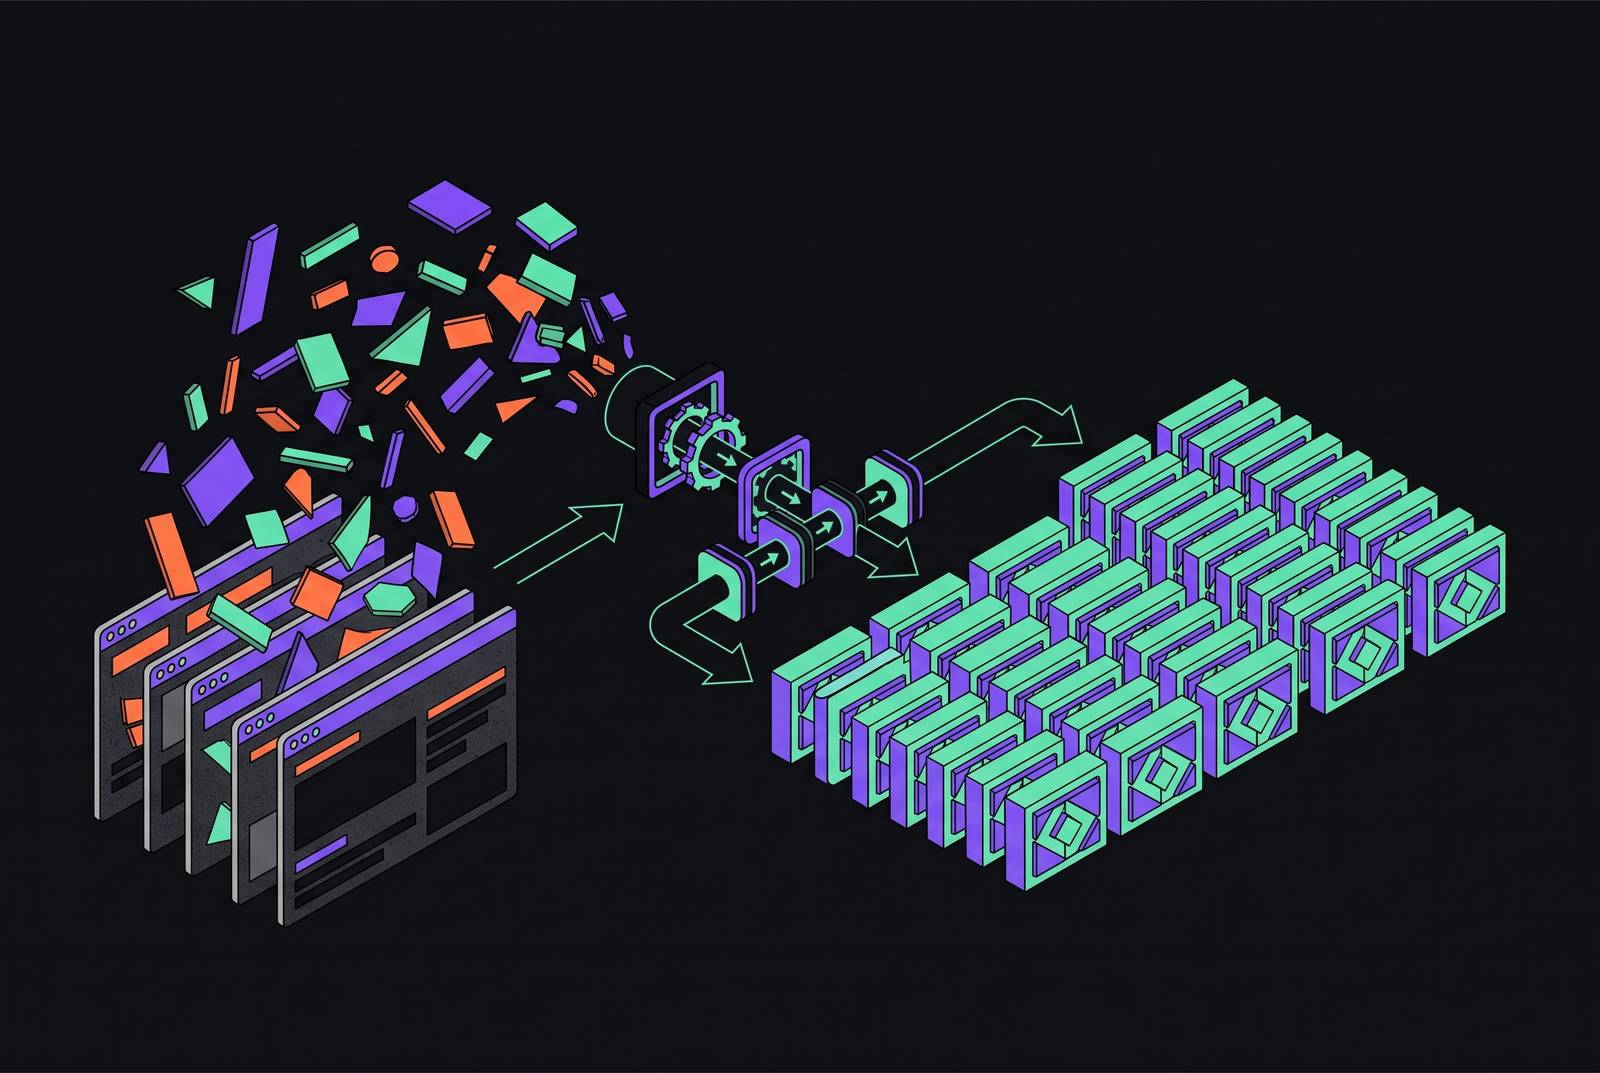
Schema extraction gets you consistent field names. It says nothing about what's sitting inside those fields. A schema tells an extraction model that "price" needs to come back as a value, and the model complies, but the schema itself doesn't specify whether that value appears in the source as "$1,200", "1200.00", "1,200 USD", or a flat null because the page hides pricing until checkout. All four are schema-valid. None of them are comparable. That gap between structural consistency and value consistency is where normalization lives, and skipping it is how AI pipelines end up with datasets that look clean and work like garbage.
The distinction should be nailed down early. Schema extraction fills a structure someone defined ahead of time: these keys, these types, this shape. Normalization is the separate job of making sure the values inside that structure actually agree with each other, so a price from one retailer means the same thing as a price from another. Grepsr's writeup on scraping pipelines said that skipping deduplication and normalization, or only half-doing them, produces a noisy dataset that's hard to use for anything. That's a structural failure sitting right downstream of a structural success, one that most teams don't notice until the model starts giving confident wrong answers. It's a structural failure sitting right downstream of a structural success, and most teams don't notice until the model starts giving confident wrong answers.
Where normalization sits in a web extraction pipeline
Picture five stages, in order. Extraction pulls data off the web through crawling, rendering, and fetching. Schema-driven parsing, whether that's a JSON schema constraint or an LLM producing structured output, forces the results into consistent fields. Normalization comes next. Then validation and quality checks. Then storage or delivery, wherever the data actually lands: a vector store, a database, or straight into an LLM pipeline.
Grepsr's April 2026 piece places normalization and deduplication squarely between extraction and storage, and that placement matters more than it sounds like it should. Unstructured's analysis adds a wrinkle: normalization happens twice in an AI pipeline, once during storage and again during feature prep. Get the naming and structure right early, and retrieval stays simple later. Get it wrong, and the cleanup work compounds every time someone touches the data again.
That compounding is the real cost, and it's the part most teams underweight. Anything that slips through normalization uncorrected doesn't just sit there quietly. It gets embedded into a vector store, indexed, and eventually retrieved by a model that has no idea the underlying value was garbage to begin with. By the time anyone notices, the bad value has already shaped an answer somebody read and acted on.
This is about structural and semantic normalization rather than fine-tuning a model or scaling numeric features for a classifier. That's a different discipline with a different vocabulary. What's discussed here is structural and semantic normalization, aimed at web-extracted JSON records on their way into an AI pipeline.
Field coercion: forcing extracted values into the types your pipeline expects
Coercion is the mechanical part: taking a string that landed in a field typed as a number, date, boolean, or enum, and converting it into whatever canonical form the pipeline treats as truth.
Prices occur in more shapes than seems reasonable for something this simple. "$1,200," "1200.00," "1,200 USD," "from $1,200," all need currency symbols and qualifiers stripped before casting to a float. Dates arrive as "01/02/2025," "Feb 1, 2025," or "2025-02-01," and Grepsr's April 2026 guidance is blunt about the fix: convert everything to ISO 8601, and standardize time zones wherever that matters. Booleans get written as "yes"/"no," "available"/"out of stock," or "true"/"1," and every version of that needs to map to one canonical boolean or enum before it touches storage. Counts and measurements bring their own mess: "approx. 500," "~500," "500+" all force a decision, lower bound, midpoint, or null, and whichever gets picked needs to apply the same way every time.
Locale adds a trap that's easy to miss until it breaks something downstream. "1.000" means one thousand in a German locale and roughly one in an English one. Pulling data from international sites means detecting locale before any numeric coercion happens, not after.
Coercion actually gets dangerous when it fails silently, and silent failure is worse than a crash. A field typed as an integer that receives "N/A" might coerce to zero, or it might coerce to null, depending entirely on how someone happened to code it that week. Either way, downstream aggregates are wrong if that rule never got written down anywhere. The fix isn't clever, it's just disciplined: coercion logic belongs attached to the schema definition itself, declared once, not scattered across whatever consumer happens to touch the data next.
Format standardization across text fields
Text fields carry their own flavor of mess. Grepsr's April 2026 breakdown covers the basics: converting to standard case (lowercase for comparison, title case for anything user-facing), stripping extra whitespace and the invisible Unicode characters HTML rendering leaves behind, standardizing abbreviations like "St." versus "Street," and folding categorical values across sources so "Full-time," "full time," and "FT" collapse into one label.
Addresses are the example that keeps coming up, and for good reason. Street, city, state, postal code all need separating and standardizing before records from different sources can join together, and definitely before anyone runs a geospatial query against them.
HTML leaves fingerprints that survive straight into JSON if nobody's watching: entities, leftover markdown symbols, escaped characters. Normalization has to strip these out after extraction, because schema-constrained output doesn't catch them automatically. Units bring a similar headache: "5kg," "5 kg," "11 lbs" all need unit detection and conversion to one canonical unit before two records can be compared at all.
This part is harder than it looks on paper, and here's the piece most teams get backward: they assume standardization is a mechanical lookup problem, when really it requires knowing the domain well enough to recognize what "correct" even looks like. Source pages make their own presentation choices, abbreviated state names, brand-specific spellings, locale punctuation, and schema extraction copies every one of those choices faithfully into the JSON. A lookup table alone won't catch that. Domain knowledge will.
Missing-value handling: decisions that determine what downstream systems see
Missing values from web extraction aren't random noise, and treating them like noise is a mistake that leads straight to bad imputation later. They reflect specific choices the source page made: a retailer hiding price until checkout, a listing with no review count yet because nobody's reviewed it.
Three categories exist, and each needs different handling under its own rule. Structurally absent means the field exists in the schema but the page just didn't render a value, so null is correct, as long as it's documented as such. Conditionally hidden means the value exists somewhere but requires interaction, a login, a "load more" click, a form submission, and that should get flagged as conditionally missing rather than lumped in with a plain null, so downstream agents know retrieval is actually possible. Ambiguous is the trickiest of the three: the field rendered text that doesn't resolve to a real value, "price varies," "contact for quote." The right move is pulling that literal string into a separate signal field and setting the typed field to null, rather than guessing at a number.
Imputation carries real risk here, and the instinct to fill gaps should be resisted more often than it's indulged. Filling missing numerics with means or medians injects values the source never actually published. For AI pipelines where grounding and verifiability matter, any imputation needs to be explicit, logged, and reversible rather than quietly baked in. Unstructured's June 2026 point is that schema normalization exists to keep facts consistent so retrieval and evaluation stay grounded. Missing-value handling is exactly where that grounding either holds or quietly gives out.
Deduplication: why duplicate records are an AI pipeline problem, not just a storage problem
Duplicates come from more places than a single bad scrape. Grepsr's piece lists the usual suspects: multiple scraping runs hitting the same source, overlapping datasets pulled from different sites, pagination inconsistencies, small variations in how the same entity gets represented across pages.
Two kinds need distinguishing, and they call for different tools. Exact duplicates have identical field values and get caught easily with hashing, cheap and simple. Near duplicates are the harder case: the same product listed on two retailer pages with slightly different titles, slightly different prices, different image URLs. Catching those takes fuzzy matching, entity resolution, similarity scoring, real engineering work rather than a one-line check.
For AI pipelines specifically, duplicates aren't just wasted storage space. The actual cost is that duplicate facts create disagreement inside the data layer itself, two rows claiming two different values for what should be one truth, and nothing downstream can tell which one to believe.
Techniques split by situation, not by preference. Hashing and signatures handle exact matching at scale, cheaply. Fuzzy matching (string similarity, token matching) handles near duplicates. Entity resolution, combining name similarity with address matching and other contextual attributes, handles records pulled from genuinely different sources describing the same thing. Comparing every record against every other record doesn't scale once a dataset gets large, so blocking and indexing strategies need to run before similarity scoring even starts, not after.
How input format to the extraction model affects how much normalization you need afterward
The format fed into the extraction model changes how much cleanup happens afterward, and the effect is bigger than most people assume. Research from Wordbricks on LLM preprocessing (the NEXT-EVAL work, 2025) compared HTML slimming, hierarchical JSON, and flat JSON as input formats, and found the choice meaningfully shifts both extraction accuracy and how often the model hallucinates.
Flat JSON let models hit an F1 score of 0.9567 with minimal hallucination, beating both slimmed HTML and hierarchical JSON. The format closest to the original HTML wasn't the best choice, which cuts against the instinct that preserving structure preserves fidelity. Sometimes flattening the structure is what protects the model from itself.
HTML slimming strips navigation, scripts, ads, tracking markup, and repeated site furniture, the same boilerplate Unstructured's analysis flags as a contaminant in extraction generally. The implication for normalization is direct: cleaner input means less hallucination and more accurate field population, which shrinks the normalization burden on the back end, specifically the missing values and type errors that extraction itself introduces rather than ones the source page actually contains.
A separate approach, SCRIBES, out of Stanford and Meta in 2025, tackles the same problem from a different angle: generating reusable extraction scripts that exploit layout similarity across pages on the same site. It beat strong baselines by over 13% on script quality, which reduces page-to-page variance that normalization would otherwise have to absorb one record at a time. Normalization gets easier when extraction gets cleaner, full stop. Investing in input preprocessing is part of normalization strategy, not separate from it. Call it upstream normalization, done before the data ever reaches the layer officially wearing that name.
Schema accuracy improvements that reduce what normalization has to repair
Most tools still treat JSON schemas as static contracts, written for a human developer to read, not for a language model to reason over. That mismatch is a root cause, not a symptom: an ambiguous or incomplete schema produces hallucinations and unreliable agent behavior upstream of everything normalization later has to clean up.
Amazon's PARSE framework, presented at ACL EMNLP 2025, tackles this directly with two components. ARCHITECT autonomously optimizes JSON schemas for LLM consumption while keeping backward compatibility through RELAY, an integrated code-generation layer. SCOPE handles reflection-based extraction, combining static guardrails with LLM-based ones.
On the SWDE benchmark, extraction accuracy improved by up to 64.7%, models saw a 10% combined improvement, and first-retry extraction errors dropped by 92%. That last number is the one that matters most for normalization. A 92% drop in first-retry errors means far fewer malformed values reach the normalization layer in the first place. Normalization spends its time on genuine edge cases instead of routine failures that never should have happened.
Schemas refined for LLM consumption produce output already closer to the target format, so there's less coercion needed, fewer nulls from fields the model misread, less stray text debris sitting in fields typed as numbers or dates. Schema design is a normalization-cost decision that gets settled before normalization starts. Ambiguous field names and underspecified enums generate cleanup work on every single run, forever, until someone fixes the schema instead of the output.
Normalization for RAG: why freshness and cleanliness are the same requirement
A RAG system is only as good as what it retrieves, full stop. The principle holds: raw OCR text or poorly chunked content dumped straight into a vector store produces noisy retrieval, because chunks that ignore document structure return the wrong pieces at the wrong time.
Normalization failures appear in retrieval as retrieval failures, and they're traceable once you know what to look for. Duplicate chunks retrieved at query time inflate how confident a claim looks, when the source only ever said it once. Dates and prices that were never normalized mislead the model about what's actually current. Inconsistent entity names across chunks, the same company spelled two different ways, stop the model from recognizing it's looking at one thing instead of two.
Live web data makes all of this harder, not easier. A real-time crawl surfaces pages where the price changed this morning and the description got rewritten last week, and normalization has to resolve version conflicts whenever the same URL gets crawled more than once. There's no getting around that with a one-time cleanup pass. The data keeps moving, so the normalization has to keep moving with it.
Unstructured's June 2026 framing gets at why this matters as much as it does: schema normalization keeps facts consistent so retrieval and evaluation stay grounded, and the grounding RAG promises depends entirely on that layer holding up. Chunking itself is a normalization decision made from the outset. Chunk size, where the boundaries fall, how much overlap sits between neighbors, all of that shapes what a retriever actually surfaces. Treating chunking as somehow apart from normalization misses that it's the last format-standardization step before anything gets indexed.
Pulling live, normalized web data into an AI pipeline without building the infrastructure yourself
Building this in-house means building scrapers, managing rendering, handling schema extraction, and then running a full normalization layer on top of all of it. The traditional split on this kind of work ran roughly 20% building scrapers and 80% maintaining them, and that ratio alone tells you where the real cost sits: not in the build, in the upkeep.
A well-built extraction API handles a lot of this before normalization even starts: fetching and rendering pages, stripping boilerplate, converting output into clean Markdown or structured JSON, populating fields against a schema. Done right, what arrives at the normalization layer reflects genuine variance in the underlying data.
That's the real dividing line between tool categories here, and it's worth picking a side on. Some tools stop at extraction and hand back raw structured output, leaving every coercion rule, every deduplication pass, every missing-value decision to whoever builds the pipeline downstream. That approach looks cheaper on day one and gets expensive fast. Others treat normalization as part of delivery itself, which is the harder thing to build but the only version that scales. For teams running AI pipelines on live web data, that difference decides whether normalization is a design decision made once, or a maintenance bill paid every single day the data keeps changing.