LLM-Ready Output Formats for External Data Sources
Choosing the right output format prevents wasted tokens and grounds retrieval in actual content.
An agent sent to fetch a product page gets back raw HTML: forty lines of navigation links, a cookie consent banner, three tracking scripts, and the actual product description buried somewhere past line two hundred. The agent burns tokens parsing chrome it will never use, and sometimes it reads the cookie banner as the content and answers from that. Output format, the shape in which web content arrives at a model, is the variable that decides whether that content works or fails, regardless of how good the model is. Get the format wrong and the result is wasted tokens, weaker retrieval, and answers that look confident but aren't grounded in anything real. The mismatch is at the boundary where the open web meets an LLM pipeline, and no amount of clever prompting fixes it after the fact: the fix has to happen where the content enters the system, not downstream in the model's context window. This is why scraping tools built for LLM pipelines, Context among them, convert URLs into clean Markdown right at the fetch layer instead of handing developers a pile of HTML to clean up themselves.
The Four Formats in Active Production Use
Four formats are in active use across real production pipelines today, and each carries its own cost.
Raw HTML keeps everything, noise included. That completeness earns its place only when a separate downstream stage genuinely needs the original markup. Otherwise it's the heaviest format by far: a single page can carry tens of thousands of tokens of navigation, ad slots, and script tags before the model reaches one sentence of actual content. Anti-bot walls make it worse. A captcha page or a cookie banner comes back formatted exactly like content, and the model treats it that way; Scrapfly's guide on agent scraping names this as one of the most common ways agents fail without anyone noticing.
Clean text strips all markup and is simple to produce. It drops headings, tables, code blocks, and link context along the way, all of which a model uses to understand how a document is organized and which parts matter. That trade-off makes clean text fine for keyword search or basic classification, and poor for retrieval that depends on structure.
Markdown keeps the structural skeleton, headings, lists, tables, code blocks, while cutting the verbose tags that bloat raw HTML. It reads well for humans and costs far fewer tokens than HTML; it has become the default choice for RAG ingestion, documentation pipelines, and direct prompting. Markdown still needs a consistent conversion process and a chunking plan behind it. It solves the noise problem. It does not solve where to split a document into pieces.
Structured JSON or JSONL fits source material that already has a known shape, pricing tiers, product specs, job listings, where the fields are knowable ahead of time. It lets a field get pulled out precisely, with no parsing step needed downstream, and it suits training sets, evaluation data, and batch jobs built around a schema and a validation step. Skip the schema and JSON extraction turns unpredictable fast: the schema is what makes the output usable, not a nice extra on top.
When Markdown Is the Right Default for RAG Ingestion
Markdown is the right default for RAG because it keeps the document structure retrieval depends on while keeping token counts low, and it breaks down once the data is tabular, schema-shaped, or needs to be pulled by field rather than found by similarity. At retrieval time, a chunk either carries enough context for the model to answer from it or it doesn't, and the difference usually comes down to whether structure survived the trip from source page to chunk. A heading tells a retrieved chunk whether it came from an introduction, a technical spec, or a warning callout, and that signal survives Markdown chunking in a way plain text can't preserve. Less noise at retrieval time means the model spends its attention on content instead of clutter, which raises how relevant the generated answer turns out to be. That said, Markdown still leaves chunk-boundary logic as a separate problem: a pipeline still needs explicit rules for where to split on heading levels, because format alone doesn't decide where one chunk ends and the next begins.
Markdown stops working well on pricing pages, product catalogs, and job boards, anywhere a downstream system needs to query by field, filter results, or compare entries side by side. Wide or deeply nested source tables often turn into a mess once forced into Markdown's table syntax. Document-level Markdown is the wrong tool when the actual question is "what does plan X cost. The rule for switching formats: once the question being asked is field-specific and the shape of the answer is knowable ahead of time, move from Markdown to structured JSON.
Schema-Driven JSON Extraction for Pages Where Markdown Is Insufficient
Source pages are often messy and inconsistent even when the data behind them follows a predictable shape. Defining a JSON schema ahead of time and handing it to an extraction layer pulls out field-level data that Markdown-based retrieval was never built to deliver. The contract works like this: name the target structure first, plan names, prices, features per tier, billing options, and the extractor returns data that matches it no matter how the underlying HTML is arranged. That's a different approach from cleaning up Markdown after the fact. The schema drives the extraction from the start rather than getting applied as a parsing step once the content already exists in some other form.
This also changes how the extraction gets built. Instead of writing CSS selectors that break the next time a site gets redesigned, a developer can describe in plain language what to pull, products with name, price, and availability status, and let the model do the matching. Context.dev's extraction guide lists JSON schema extraction, giving the tool a target shape and getting back data that conforms to it, as the first thing an extraction API has to prove it can do before it earns a spot in an LLM pipeline.
Validation matters just as much as the schema itself. An extractor that returns the right shape but fills it with empty or made-up fields is worse than returning nothing at all, because the failure passes silently and corrupts whatever runs downstream of it. Context.dev's structured extraction, built around a developer-defined JSON schema, speaks directly to this pattern: the schema becomes the abstraction that makes web content something an AI pipeline can consume predictably.
Live Fetch and the RAG Freshness Problem
Some data moves faster than any indexing schedule can keep up with: prices, library versions, security CVEs, regulatory rules. For that kind of data, the format of the cached version doesn't matter, because the content itself is already wrong by the time anyone retrieves it. The real fix is fetching live at query time, not formatting the stale version more carefully. A model is frozen at its training cutoff, and embedding-based RAG is frozen at whatever its last indexing run happened to capture. Both arrive at the same staleness problem through different routes. A perfectly formatted Markdown chunk describing a pricing page can do real damage if the prices changed last week and the chunk gives no hint that anything might be out of date.
Most production systems don't choose one approach over the other. They run cached, indexed content for material that doesn't move much and reserve live fetch for queries where freshness actually matters, deciding per query type rather than building one policy for the whole pipeline. Live fetch adds latency and cost on every call, and that trade-off needs to be made on purpose. A freshness TTL on cached content, paired with a trigger that refreshes when the source page actually changes, captures most of what live fetch offers without paying that latency cost on every single query. Context.dev's approach here is to handle the live fetch itself and hand back the result already in LLM-ready format at the moment an agent asks for it, rather than leaving a team to build and maintain its own refresh pipeline on top.
Agent Tool-Use and the Format Requirement at Every Pipeline Stage
An agent that calls web fetch as a tool inside a reasoning loop turns a format failure into a chain reaction. A bad fetch on step one leads to a misread on step two, a wrong replan on step three, and a cost overrun from the loop the agent runs trying to dig itself out. A traditional scraper follows a fixed set of instructions and fails the same way every time. An agent observes, reasons, and decides what to do next, so any inconsistency in how the fetched content is formatted appears as inconsistency in what the agent reasons about. Scrapfly's 2026 guide on agent scraping names unbounded retry loops as the single biggest driver of cost in agent runs, tracing many of those loops back to the fetch layer: the agent gets a bot-detection page or an empty response, can't tell what went wrong, and replans around a problem that was never a reasoning failure. An agent handed a captcha screen formatted as though it were content will try to pull product data out of it, find nothing, and burn a cycle figuring out what to do next, when the actual problem was the format of what it received.
The Model Context Protocol, MCP, helps here by giving agents a standard way to discover and invoke tools, collapsing what used to be a bespoke integration problem into something the agent already knows how to speak. That's a genuine step forward for tool discovery. It does nothing on its own for data quality: what a tool returns, and whether the agent can reason over it, still comes down to format. The right fix is a single fetch tool that returns consistently shaped, LLM-ready output, Markdown for pages that are mostly prose, JSON for anything schema-shaped, so the reasoning step always gets a predictable input no matter what the source page looked like. Context.dev's single REST API, returning either LLM-ready Markdown or structured JSON, is built around exactly that requirement: the agent gets a consistent, usable input regardless of how chaotic the original page happened to be.
Consolidating on One API That Handles Format Decisions
Stitching together a stack of separate scrapers, crawlers, and format converters multiplies the number of places where format inconsistency can creep into a pipeline, and the cost of maintaining that stack grows faster than the capability it buys. Running open-source tools instead doesn't make the cost disappear, it just moves it: self-hosting a crawler removes a subscription fee but leaves a team covering compute, proxies, storage, monitoring, and upkeep, with format consistency across all of it now the team's own problem to solve. The fragmentation tax is clearest at the hand-offs: one vendor delivers raw HTML, another converts it to Markdown, a third handles structured extraction, and when something breaks at any one of those seams, it's hard to tell which stage caused it.
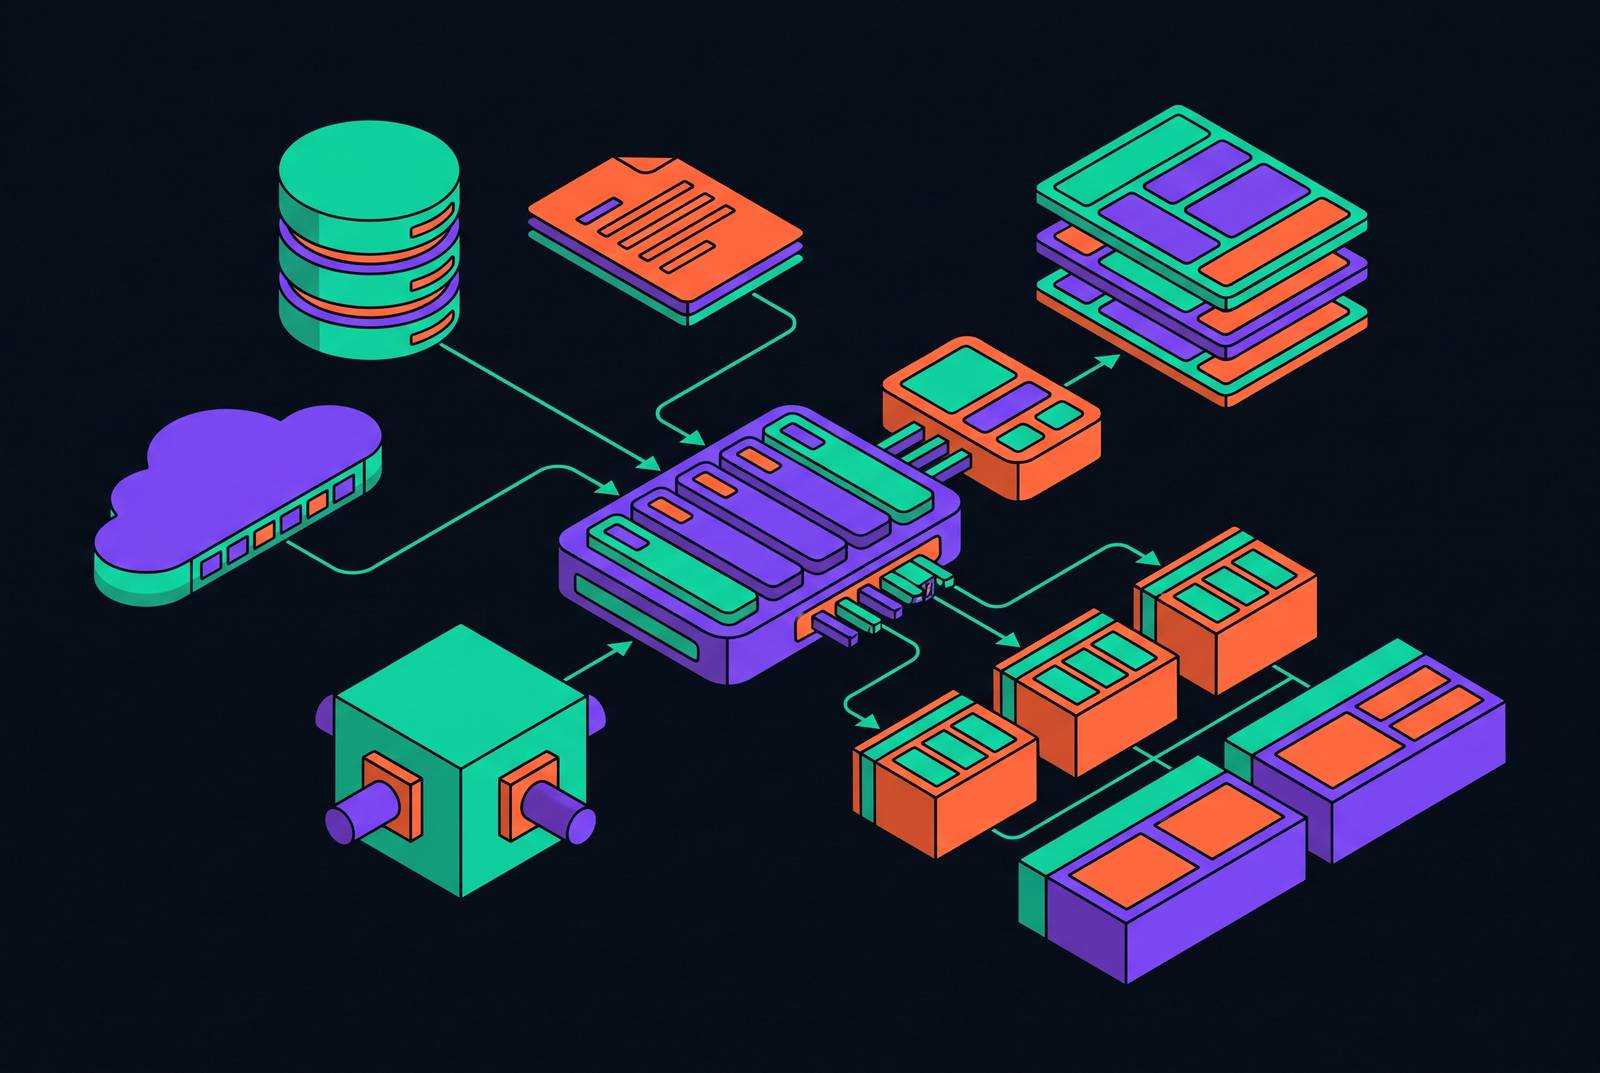
A single API that delivers Markdown for prose, structured JSON for schema-shaped data, and live fetch for anything time-sensitive consolidates those hand-offs into one place to check format quality. Context.dev's single REST API, built to convert any URL into LLM-ready Markdown, crawl full websites, and extract structured data through a JSON schema, is a direct example of this kind of consolidation. Companies including Mintlify, SiteGPT, Sourcely, and daily.dev run it as the data layer under their own products. The honest counterpoint is cost: per-request pricing at high volume can make a managed API expensive for pipelines that fire off requests constantly, and that trade-off deserves real modeling before a team commits to it. What rarely gets modeled with the same rigor is the ongoing cost of the alternative, the proxies, the monitoring, the engineer-hours spent keeping a self-built stack formatted consistently across every source it touches.
A practical decision map: which format to choose at each pipeline stage
The question at each stage of a pipeline is never which format wins in the abstract. It's what that stage consumes and what shape the data needs to be in to be useful there. Pulling content from prose-heavy sources into a RAG system calls for Markdown, since it keeps the structure intact, holds token counts down, and chunks cleanly along heading boundaries. Pulling from structured sources, pricing pages, product catalogs, spec sheets, calls for structured JSON built against a defined schema instead, because it supports field-level retrieval and filtering that similarity search over Markdown chunks simply can't do. Anywhere an agent calls web fetch as a tool inside a reasoning loop, the format needs to stay predictable across every call, Markdown for prose pages and JSON for schema-shaped ones, so the reasoning step always receives an input it can count on. Anywhere the data moves faster than an index can keep up, prices, versions, security advisories, regulatory updates, live fetch at query time replaces the cached format entirely, since stale content is wrong no matter how cleanly it's formatted. And across a stack built from several vendors handling HTML, Markdown conversion, and extraction separately, consolidating onto one API that handles all three removes the hand-off points where format inconsistency does the most damage, giving a team a single place to check and trust the shape of what its pipeline is actually fed.