Parsing Job Listings Into Structured Records for AI Workflows
Converting messy job listings into clean data that AI systems can actually use.
Job descriptions get written for people, not for databases. None of these are wrong. Each one makes sense inside that company's internal leveling system.
The same looseness appears throughout the rest of a posting. Location might read "London, UK," or "Greater London area," or "Hybrid, a few days in office," or just "Remote," with no consistent format tying any of those phrases together. From a pipeline's side, it's a mess that breaks anything built to read it at scale.
Searching across listings instead of reading one at a time raises the cost of relying on keyword matching. If a board parses listings into structured fields before anyone searches them, it returns every matching role no matter how the original posting phrased it. That gap between keyword matching and parsed retrieval is the reason this entire piece exists: turning prose into fields that downstream systems can actually read.
The three stages between raw prose and a queryable record
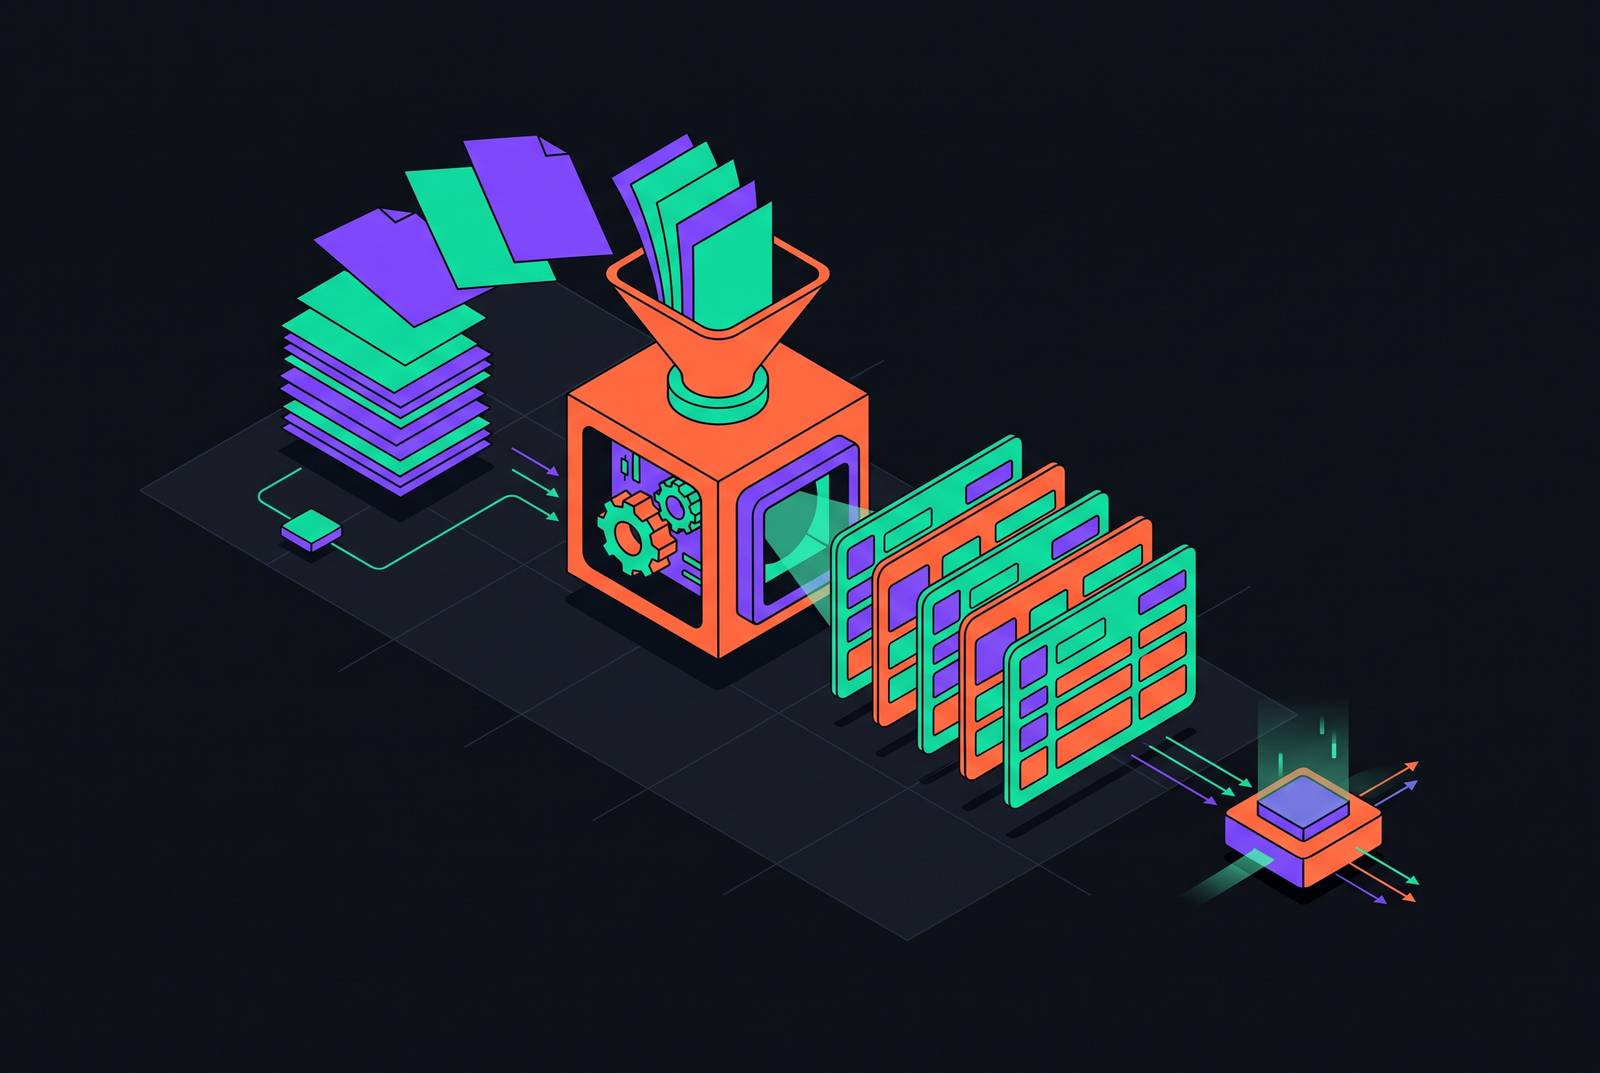
Parsing breaks down into three steps, and each step depends on the one before it finishing correctly. Skipping the order or treating these stages as interchangeable is how pipelines end up producing garbage downstream without anyone noticing until much later.
The first stage is text extraction: pulling raw prose out of wherever it lives, whether that's an HTML page, a PDF, or an API response. A plain HTTP request won't surface text that a page only builds after the browser runs its scripts, so a huge share of modern career sites simply won't show up correctly without a crawler built for that.
The second stage is classification: taking the extracted text and figuring out which parts of it correspond to which fields. This is where most of the real analytical work in the pipeline happens.
The third stage is taxonomy mapping: taking the values pulled out in stage two and normalizing them against a standard set of terms. None of this works without the earlier stages feeding it clean input, and none of the earlier stages matter if nothing maps the output to a shared vocabulary afterward.
One distinction carries weight here: parsed data is structured, but it isn't validated. Checking facts, catching duplicate postings, and confirming a listing hasn't expired are separate jobs further down the pipeline. That distinction matters later, when freshness and monitoring come up.
CSS selectors as the wrong abstraction for multi-source job data
The traditional way to pull data off a website ties the extraction logic directly to that site's markup. Multiply that across every job board a pipeline touches and a team ends up maintaining a growing pile of one-off rules, one per site, each one fragile in its own way.
Covering more sources makes a pipeline more likely to break. No error gets thrown. It just starts producing wrong data that looks plausible enough to pass unnoticed.
A reasonable objection says: we only scrape a handful of boards, so keeping up with a few rule changes is manageable. That holds up until the goal becomes feeding AI systems. Those systems need consistent field names and consistent formats across every source they touch. A pile of site-specific scrapers can't deliver that consistency without an added normalization layer, one that ends up just as complicated as the scraping work it was supposed to replace.
Schema-driven extraction as the abstraction that replaces site-specific logic
Schema-based extraction flips the whole approach around. Instead of writing a rule for where data sits on one specific page, a developer defines the fields they actually need, and the extraction layer figures out where those values live on whatever page it's looking at. The same schema then works across different job boards, different career pages, and different applicant tracking platforms, as long as the sites carry similar kinds of data.
The productive question in this model is what fields every downstream AI workflow actually needs, not what the page's HTML looks like. A working job schema built around that question typically includes the job title in normalized form, required skills split out from preferred skills and typed by category (technical, soft, certification), experience level, location paired with a remote or hybrid status flag, salary normalized to an annual figure, employment type (full-time, contract, part-time), education requirements including whether equivalent experience is accepted in place of a degree, and company-level details like name, industry, and listed benefits. That's a working schema, not a loose collection of fields: each one answers a specific question a downstream system will actually ask.
The well-built versions of these parsers combine large language models with rule-based logic. The model handles novel phrasing and layout variation, the kind of thing that breaks a rigid rule-based system the first time a job board phrases something unexpectedly. So the rule-based logic enforces consistent field boundaries and output formats, and the schema's structure holds even when the model is doing the reading.
Some career pages already carry structured job data through Schema.org's JobPosting format, written in JSON-LD. That sounds like it should solve the whole problem on its own, but most AI crawlers don't actually read that markup. If nothing downstream reads that schema sitting in a script tag, the extraction problem remains unsolved. The extraction layer still has to pull structured values out of the visible page itself.
What the extraction pipeline needs beyond the schema
A well-designed schema only produces good output when the text extraction stage feeding it delivers the right content.
Company career pages are the original source for most job listings, and they're built in wildly different ways. A crawler that can't execute JavaScript returns an empty page on a large share of these sites, so the extraction schema never even gets a chance to run because there's no text there to read.
Format diversity goes beyond rendering, too. A capable job description parser needs to accept plain text, HTML, PDF, and DOCX, because job data doesn't only arrive as scraped web pages. It comes in through applicant tracking system exports, email attachments, and document uploads, and a pipeline that only handles one format will miss a meaningful share of the data it's supposed to be processing.
The most serious risk in all of this is the silent failure. Nothing crashes. Nothing throws an error. The schema receives a string that looks like reasonable data and has no way of knowing it's wrong, and that bad record flows straight into every downstream system that trusts it.
Structured job records in matching, RAG, and agentic pipelines
Structured records work better than prose for the systems that actually consume job data, because those systems are built to call functions, match candidates, and write to databases, all of which need specific fields rather than paragraphs an LLM has to re-read and re-interpret every time.
Candidate matching is the clearest case. Every time the matching system runs a comparison, a paragraph of prose forces it to re-extract the same information, repeating work that parsing already did once.
Structured data also maps directly onto database rows, with no extra translation step needed. Running that same query against raw prose turns it into a separate, expensive LLM call for every listing being checked, just to figure out whether each one mentions Python and Berlin.
Retrieval-augmented generation pipelines face a freshness problem that structured extraction directly addresses. A live crawl paired with a defined schema solves this at the architecture level: each crawl cycle replaces stale structured records with fresh ones automatically, so the data a RAG system retrieves reflects the current market rather than a snapshot from whenever the pipeline last ran well.
Agentic workflows depend on the same foundation. If you hand it structured records, it can compare fields directly and move straight to the actual task.
One distinction inside the schema matters specifically for matching: separating required skills from preferred skills. A parser that tells these two apart produces records a matching algorithm can weight correctly, treating a required skill as a hard filter and a preferred one as a soft bonus, rather than treating every mentioned skill as equally mandatory and rejecting good candidates over a nice-to-have.
Keeping structured records fresh: change detection, expiry, and continuous pipeline integrity
A pipeline can produce clean structured records on day one, but it won't stay clean without ongoing attention.
Job data freshness is an ongoing problem, not something solved once at extraction time. Ghost jobs, postings that stay live after the role is no longer actually open, account for 18 to 22% of postings across major boards. A production pipeline needs change detection running at the source level, checking whether the page structure the extraction schema depends on has shifted, not just whether the field values that came out this time differ from last time.
Agentic data quality monitoring approaches this differently than older rule-based checks do. Instead of waiting for a fixed rule to get violated, a monitoring system continuously profiles what a "normal" extracted record looks like for a given source and flags deviations from that baseline. A sudden drop in how often the salary field gets populated for listings from one particular job board is a strong early signal that the page layout changed before anyone downstream notices broken or missing data.
The design lesson for schemas is direct: build in metadata fields from the start. Date extracted, source URL, date posted, and valid-through date all need a place in the schema, because without them, expiry logic and freshness checks have nothing to run against. A schema that tracks when a record was pulled and how long it's supposed to stay valid can tell whether a record is still worth trusting or has quietly gone stale.
Enriching job records with company data: turning a parsed listing into something a downstream system can act on
A parsed job listing is still missing half the picture if it has no company-level data attached. Pulling that information is its own extraction problem, separate from parsing the job description itself, and it needs its own schema and its own set of crawl targets.
Company information worth gathering includes details pulled from financial reports, news coverage, and other business intelligence sources about how a company is doing and where its hiring needs are headed. None of that lives inside the job posting itself. It has to come from a different set of sources entirely, crawled and structured on its own track.
Brand details matter here too: logos, brand colors, fonts, and social media presence. None of it appears in the text of a job description. It has to be pulled from the employer's own web presence directly.
The schema implication is straightforward: company data belongs in its own linked record, not copied into every job listing that mentions that employer. A single company appears across dozens of open roles at once, so maintaining one enriched company record that every relevant listing points back to is both more efficient and more consistent than re-extracting the same company details over and over for each individual posting.
Building the extraction pipeline with an API rather than bespoke infrastructure
Add up everything described so far: JavaScript-capable crawling, schema-driven extraction, taxonomy normalization, ongoing change detection, and company enrichment. That's a substantial amount of infrastructure, and most teams underestimate how much work it is until they've already started building it.
Each layer in that stack has its own failure modes and needs its own maintenance schedule. None of these are one-time costs. Each one runs continuously for as long as the pipeline stays in production.
An API-first approach collapses all of that into one call. A single REST API that takes a URL and returns LLM-ready Markdown or structured JSON, built against a schema the developer defines, handles crawling, rendering, and extraction in that one request. The crawling fleet, the rendering engine, and the extraction logic sit behind the API, not inside a team's own codebase.
Most integrations with a well-built job description parsing API reach staging within one to two days. The model is simple: send a job description in a POST request, get back structured JSON. A team goes from nothing to working extraction without building or maintaining any of the crawling and rendering infrastructure sitting underneath it.
You might object that you want custom control over extraction logic, and that's a fair concern to raise. The schema stays portable and adjustable. The infrastructure underneath it doesn't have to be rebuilt every time that schema changes.
Designing a job data schema that works across sources and holds up in production
A schema that actually holds up in production isn't just a list of field names; it's a set of decisions about types, cardinality, normalization, and which fields are optional, and those decisions decide whether downstream systems can use the output straight away or need a custom adapter built for every single source.
Start with title: extract it raw as written, and normalize it to a standard taxonomy as a separate field. And metadata, date extracted, source URL, date posted, and valid-through date, needs to sit in the schema from the start, since those fields are what make freshness checks and duplicate detection possible later.
Schema versioning deserves attention from day one, not as an afterthought once something breaks. Planning for that from the beginning avoids breaking changes landing on production data later.
The real payoff compounds over time. If a schema works across LinkedIn, Glassdoor, Upwork, and direct employer career pages, it can handle a brand-new source added six months down the line. The schema itself stays exactly as it was. That stability is the entire argument: getting the schema right once is the investment that pays off every single time a new source gets added afterward.